




ResearchRabbit
A research tool for discovering, organizing, and tracking academic literature through relationship diagrams
Tags:AI learning websitesWhat is ResearchRabbit?
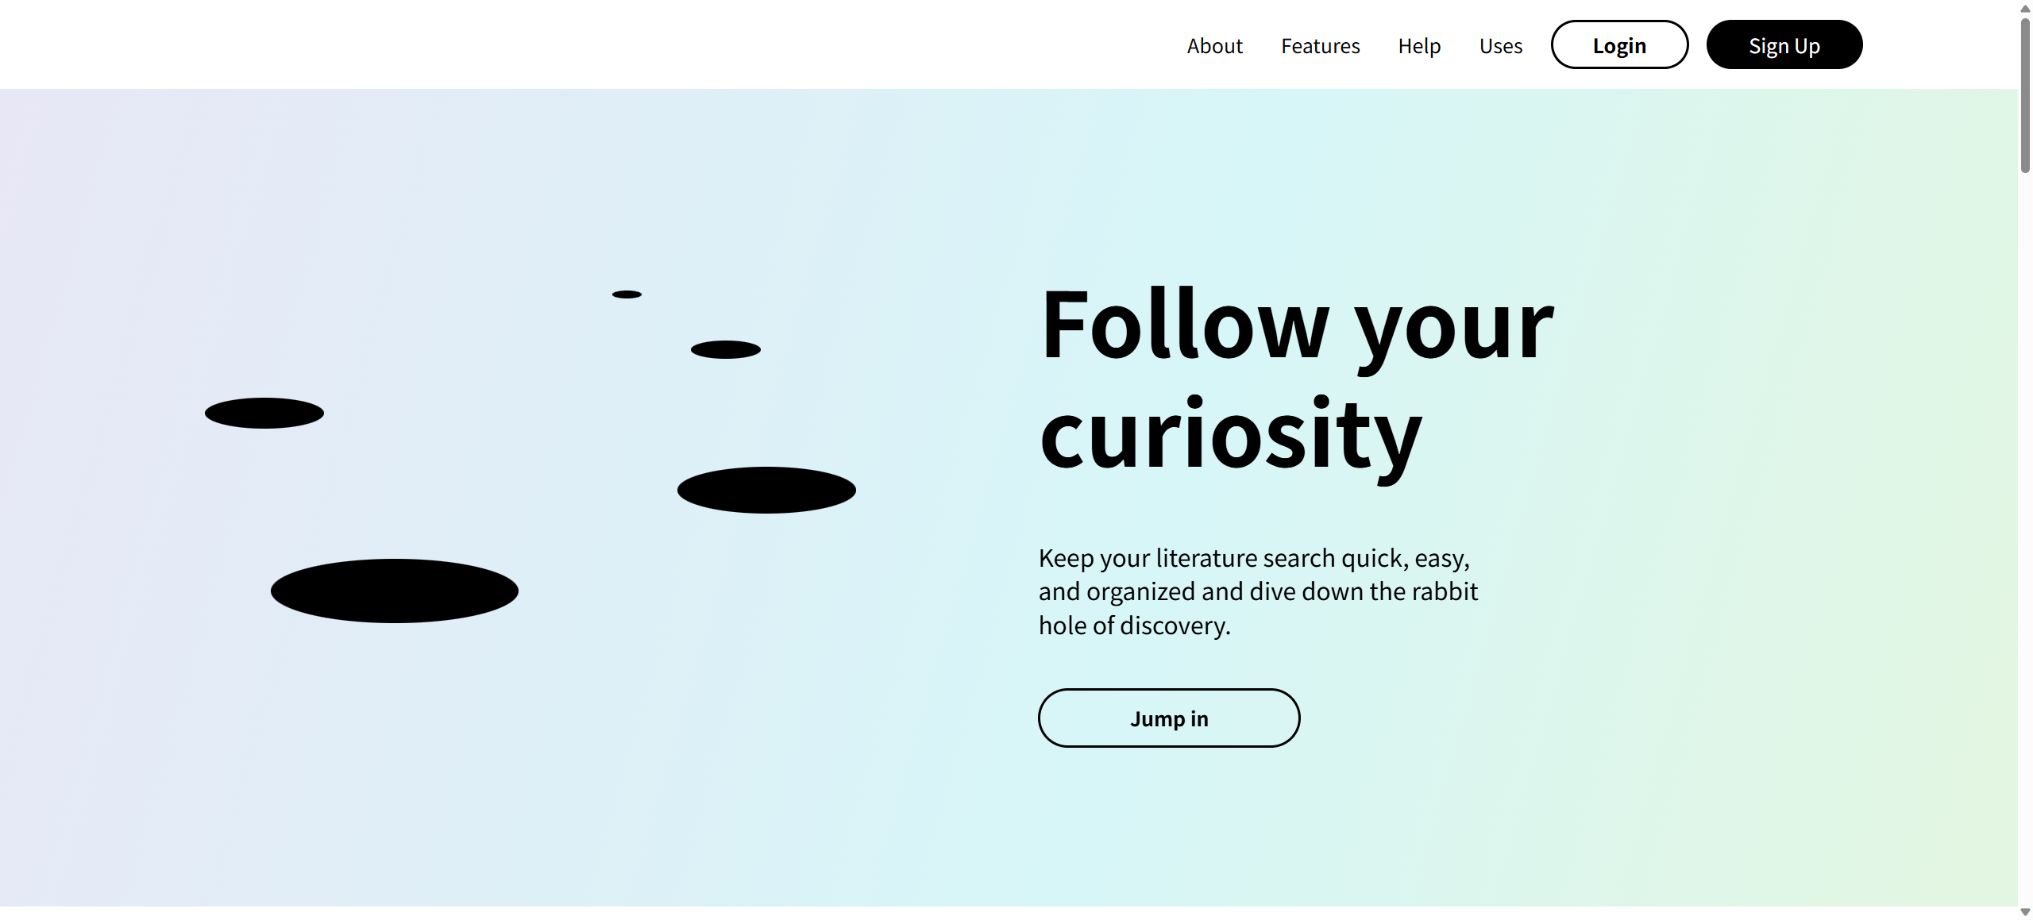
ResearchRabbit is a tool for discovering and visualizing academic literature, designed for students, researchers, and teams conducting systematic reviews. It views papers as part of an interconnected research network, allowing users to start from a small number of known papers and expand their search by following citations, references, co-citations, authors, and similar studies, rather than merely providing a list of results based on keywords.
It is particularly suitable for the \"snowballing\" phase that follows traditional database searches: first, identify a few reliable seminal papers, then trace back to earlier foundational studies, the papers that cite them, related research works, and key authors; finally, save the valuable results in a collection and export them to a reference management software.
How does ResearchRabbit use AI?
According to the official information, ResearchRabbit’s core recommendation algorithm does not rely on large language models to generate answers. Keyword, DOI, and title searches utilize precomputed indexes and graph-based methods, while subsequent recommendations are based on an analysis of citations, references, co-citations, shared citations, as well as author and co-author relationships.
The advantage of this approach is that the recommendations are based on relatively transparent criteria, and the results can be verified by referring to the actual papers and their network connections; it also prevents generative summaries from inventing non-existent papers or citations. It still uses algorithms to analyze users’ browsing and saving behaviors, but its main goal is to identify relevant literature, rather than replacing researchers in writing conclusions.
Database with over 310 million papers
The current official documentation states that the database includes over 310 million academic papers; its data source consists of academic metadata providers such as Semantic Scholar, Crossref, and OpenAlex, with coverage being expanded through partnerships with Litmaps.
A large number of databases does not mean that all records are complete. Some papers may lack abstracts, references, citation relationships, or proper author information; errors may also occur when authors with the same name are combined together.
ResearchRabbit mainly provides functions for searching and accessing metadata; it does not guarantee that the full text of each paper is available for download.
Search by keywords, title, and DOI
Users can enter keywords, research questions, paper titles, or DOIs to start a search. The results will show information such as the title, authors, year of publication, and citation count, which makes it possible to identify 1 to 3 highly relevant papers as a starting point.
Keyword search is suitable for creating an initial set of articles, but the true value of ResearchRabbit lies in the online exploration that can be carried out once the appropriate papers have been selected. For systematic reviews, it is still necessary to develop reproducible Boolean search queries in databases such as Web of Science, Scopus, PubMed, JSTOR, or discipline-specific databases, and then use ResearchRabbit to conduct further citation tracking.
Seed papers and iterative discovery
The seed papers serve as a starting point for further recommendations. The free version allows up to 50 seed papers to be used at a time, while the RR+ version permits 300 such papers; this is suitable for using a complete set of papers for initial screening in order to identify missing items, cross-cutting topics, and marginal studies.
Seed quality has a direct impact on the recommendations. If papers with vague topics, different methods, or low relevance are mixed together, the results may deviate from the actual issue at hand.
A more reliable approach is to create small, well-structured sets of seed items based on sub-topics, methods, or research questions, and to review and save them in successive rounds.
Similar papers
Similar Work recommends related studies based on the relationships of the current set of papers within the research network, and it is able to identify papers that use different terminology but have similar citation patterns. For interdisciplinary research, it often helps to fill in the gaps left by simple keyword searches.
Similarity does not mean that the research conclusions are identical. Users still need to read the abstract, methods, sample data, research subjects, and the full text; they cannot assume that two papers can be combined simply because their diagrams are located near each other.
Early research and subsequent research
Early Work helps track the prior literature and earlier foundational works cited in a paper, while Later Work shows the studies that have cited that paper later on.
Forward and backward citation tracking allows one to understand how concepts are formed, how methods evolve, and whether a particular conclusion is later verified or challenged.
It takes time for new papers to accumulate citations, and a low number of citations may simply be due to their recent publication. When assessing impact, factors such as the year of publication, the citation patterns in the respective field, the quality of the journal, and the quality of the research itself should be taken into account, rather than relying solely on the number of citations.
Interactive reference graph
ResearchRabbit presents papers as nodes and citation relationships as connections, allowing one to understand the development of research in terms of time and impact. Users can identify theme clusters, bridging papers, key authors, and research gaps, which is a more intuitive approach than scrolling through long lists one paper at a time.
Maps are tools for exploration and communication, not strict quantitative conclusions. The size, position of nodes, and clustering depend on the current selections as well as the completeness of the data;
If the diagram is included in a paper, poster, or presentation, the software used should be indicated according to the requirements of the publisher.
Authors and collaboration networks
In addition to the relationship between papers, the platform also allows users to explore research groups based on author and co-author relationships, identify the key scholars who continuously publish on a particular topic, and view their related works. It is very useful for finding potential supervisors, collaboration partners, or an overview of the development trends in a given field.
Name disambiguation is not always accurate, especially with common names, changes in institutional affiliations, and different spellings. When citing an author’s work formally or conducting research evaluations, it is necessary to verify the information using ORCID, the institution’s website, and the original paper.
Collections and subsets
Users can save papers in Collections, and organize them using Subcollections based on theory, methods, experiments, sections to be read, or sections to be written. Recently Found allows for temporarily storing papers discovered during exploration, with the option to move them to official collections after further selection.
A collection is not just a simple folder – it can also serve as an input for new searches. Properly defined boundaries for collections help improve the quality of subsequent recommendations.
If a collection contains multiple unrelated topics, it is recommended to split it and search for each topic separately.
Notes, stickers, and colors
The platform allows users to take notes alongside the papers, and to establish a personal sorting system using stickers and colors; for example, to mark items as “to include,” “to exclude,” “require the full text,” “related to methods,” or “at risk of bias.” This information helps reduce the time needed to re-understand the papers during the writing phase.
Notes represent the user’s own research judgments and do not replace standardized data extraction tables. A systematic review should also include the reasons for exclusion, the dates of searching, the databases used, the complete search queries, and records of how duplicate entries were handled.
Sharing collections and team collaboration
The free version allows you to invite collaborators, designate viewers or editors, and create public viewing links. A shared collection includes its subcollections and notes, making it suitable for team members to jointly select materials, for instructors to provide feedback, or for sharing reading lists with classmates.
Before sharing, check whether the notes contain unpublished ideas, peer-review content, or personal information. For sensitive materials, use controlled invitations instead of creating public links directly.
Zotero import
ResearchRabbit offers a Zotero importer. The first time you connect, you need to be authorized to access Zotero’s collections; thereafter, you can select accounts, collections, and individual papers to import into ResearchRabbit, using these existing documents as a starting point for discovering new papers.
According to the current official instructions, Zotero is primarily used for importing data; bringing newly found materials into Zotero can be done by exporting them in BibTeX format.
Two-way synchronization is still an area under continuous development; the existing functions should not be described as real-time two-way synchronization.
BibTeX, RIS, and CSV import/export
Collections can be exported in BibTeX, RIS, or CSV format, making it easy to transfer them to Zotero, EndNote, Mendeley, and other research tools. Data from EndNote and Mendeley can also be exported as BibTeX first and then uploaded to ResearchRabbit.
What is exported are the bibliographic records, not the full texts that are protected by copyright. After importing, it is necessary to check the DOI, the order of authors, page numbers, the volume and issue numbers of the journal, as well as any special characters, in order to avoid issues resulting from missing metadata that could affect the final reference list.
Copy the citation format
Users can select a citation style from the paper menu and copy the formatted citation for quick sharing or temporary notes. For formal papers, it is still recommended to generate citations uniformly using a reference manager, and to verify them against the journal’s requirements and the layout of the paper’s first page.
Multilingual use
ResearchRabbit can be used to search for academic records in various languages, and its interface also offers multilingual options. Chinese users can enter Chinese keywords or import Chinese papers; however, the scope of results and the availability of citation data depend on whether data providers include relevant information and provide standardized metadata.
For Chinese core journals, dissertations, and data from local databases, it is necessary to use sources such as CNKI, Wanfang, VIP, or the university’s own database. ResearchRabbit cannot replace the comprehensive search capabilities of specialized Chinese databases.
Price and version comparison
| Package or version | Prices, quotas, and core benefits |
|---|---|
| What is included in the free version? | The Free Forever version costs $0; it includes unlimited searches, access to any number of databases and collections, the ability to collaborate and share content, uploading documents to databases, viewing citations and similar papers, access to citation maps, notes and color coding, as well as the possibility to search for up to 50 reference papers. The free version is sufficient for conducting focused literature reviews, and the provider has committed to maintaining this free tier in the long term. The limitations lie mainly in the number of reference papers that can be used for large-scale searches, in advanced filtering options, and in the ability to isolate different projects, rather than in restricting the core mapping functions. |
| ResearchRabbit+ price | ResearchRabbit+ costs $12.5 per month or $120 per year, which is equivalent to $10 per month; this represents a savings of about 20% compared to the monthly subscription price. More than 100 countries and regions, including China, can take advantage of parity discounts on the upgrade page – the specific discount codes and amounts are available after logging in. RR+ is suitable for users who need to conduct large-scale reviews, multiple parallel research projects, or require precise control over their searches. The subscription fee helps to keep the free tier operational, but it isn’t necessary for every researcher to upgrade. |
What is included in the free version?
The Free Forever plan costs $0 and includes unlimited searches, access to any number of databases and collections, collaborative sharing, the ability to upload documents to databases, viewing of citations and similar papers, citation maps, notes and color coding, as well as the possibility to search for up to 50 reference papers.
The free version is sufficient for carrying out focused literature reviews, and the developers have committed to maintaining this free tier in the long term. The limitations lie mainly in the number of search terms that can be used for large-scale searches, as well as in advanced filtering options and the ability to isolate different projects, rather than in the restriction of core mapping functions.
ResearchRabbit+ price
ResearchRabbit+ costs $12.5 per month if paid on a monthly basis, or $120 per year, which is equivalent to $10 per month; this represents a savings of about 20% compared to the monthly payment option. More than 100 countries and regions, including China, can take advantage of parity-based discounts on the upgrade page; the specific discount codes and amounts can be viewed after logging in.
RR+ is suitable for large-scale reviews, multiple parallel research projects, and users who need precise control over the search process. The subscription fee helps to keep the free version operational, but it isn’t necessary for every researcher to upgrade.
RR+ Advanced Search
The paid version offers more precise controls over keywords, journals, and date ranges; it enables the identification of thematic overlaps, focuses on niche areas, excludes irrelevant subfields, and helps to spot any connections that might have been missed in a review.
Advanced filtering improves efficiency, but it cannot automatically ensure that all relevant results are retrieved. Systematic reviews should still document all criteria and the filtering processes, with at least one researcher reviewing the key findings.
RR+ multiple items
Multiple Projects allows for the separate management of articles, collections, and notes related to different papers or projects, thereby preventing the storage actions related to one topic from affecting the recommendations for another topic. For users who are working on multiple papers at the same time or overseeing several projects, this approach is more organized than keeping a large number of collections in the same library.
Study of integrity signals and alerts
The RR+ pricing page lists Signals alerts, which are intended to provide information related to the integrity of research and to reduce the risk of omissions. Such signals should serve as clues for further verification; they cannot replace databases of withdrawn papers, journal notifications, or manual assessments of research quality.
Institutional plan
Institution offers customized pricing that includes RR+ capabilities, bulk discounts, integration with research libraries via LibKey, user management, usage statistics, and dedicated support. When purchasing from these services, universities or research institutions need to clarify the aspects related to authentication, library collection integration, data processing, account migration, and usage analysis.
The relationship between ResearchRabbit and databases
ResearchRabbit officially recommends using it in conjunction with library databases. Traditional databases are adept at structured searching, subject indexing, full-text retrieval, and reproducible searches.
ResearchRabbit is adept at performing network discovery, visualization, and iterative expansion based on existing papers.
The most reliable workflow is to first establish reproducible searches in specialized databases, then import the relevant or key papers into ResearchRabbit for forward and backward tracking, and finally obtain the full texts from the institution’s collection or the publisher’s website.
Is it possible to download the full text of the paper?
ResearchRabbit primarily displays paper metadata, abstracts, and external access links; it is not a tool for downloading full texts in order to bypass paywalls. The availability of the full texts depends on whether they are in the public domain, provided by publishers, archived by authors, or available through subscriptions by the respective institutions.
When encountering paid papers, one can try to find them through the university library, interlibrary loan services, public versions provided by the authors, or legitimate open-access sources; however, the fact that a record is found does not mean that authorization to access the full text has been obtained.
ResearchRabbit Usage Guide
Complete a basic task.
- Clarify the issue, time frame, location, source priority, and output format;
- Upload materials for which you have permission to use in ResearchRabbit, or enter search queries;
- First, learn how to use AI with ResearchRabbit: establish a framework and then supplement it with evidence from a database of over 100 million papers.
- It is necessary to distinguish between factual information from the source, the author’s opinions, and AI-generated conclusions.
- Check each item for dates, numbers, the original location, and any conflicting evidence;
- The conclusions are manually revised, the verification time is recorded, and then they are published;
Create reusable professional workflows
- Break down complex topics into four categories of questions: background, data, comparison, and conclusions;
- How does ResearchRabbit utilize AI? A set of fixed research procedures is established through a database of over 100 million papers, as well as searches using keywords, titles, and DOIs.
- Give priority to using the official website, research papers, regulatory documents, and raw data;
- A second person is assigned to review conclusions that are considered high-risk;
- Save queries, evidence, versions, and unresolved issues;
- Re-run after the data changes and update the conclusions;
Is it suitable for a systematic review?
- It is suitable for supplementing citation tracking, identifying omissions, and understanding research networks, but it should not be the only database used for systematic reviews;
- Relying solely on network algorithms may favor studies with extensive citations, complete metadata, or established networks, and it may also underestimate newly published works as well as literature from less prominent regions.
- A systematic review requires a pre-registration protocol, multiple databases, repeated screening, quality assessment, and PRISMA reporting;
- ResearchRabbit can save the process of making discoveries, but it cannot automatically fulfill all compliance requirements;
GitHub and the open-source status
The core search, graph analysis, web applications, and recommendation algorithms of ResearchRabbit are not open-source products. The official GitHub repository currently exposes only a Python client branch related to the Amplitude analytics service; the complete source code for the ResearchRabbit platform has not been made available.
The local research agents, downloaders, and LangGraph projects available on GitHub under the name research-rabbit are mostly third-party or other products; they have no connection to this tool for creating academic citation networks. Such applications should be classified as closed-source SaaS services, and it cannot be assumed that they can be deployed privately just because there are repositories with the same name.
Which users is it suitable for?
- Students preparing course papers, graduation theses, and doctoral dissertations;
- Researchers who conduct narrative reviews, scoping reviews, or systematic reviews;
- It is necessary to identify foundational papers, the most recent studies, and teams with interdisciplinary connections;
- Users who use Zotero, EndNote, or Mendeley to manage references;
- Research teams that need to share reading lists and notes with supervisors and collaborators;
- Teachers who wish to use diagrams to illustrate the research trajectory and author networks.
Product advantages
- The free version retains all the core capabilities for document discovery and mapping;
- The database contains over 310 million papers, offering a wide range of topics;
- By searching the Internet, it is possible to find various related studies in which different keywords are used.
- The core recommendations do not rely on large language models to generate content;
- Supports Collections, notes, collaboration, and public sharing;
- It can be integrated with Zotero and BibTeX research workflows.
Restrictions and Precautions
- Metadata, citations, and author disambiguation may be incomplete, and recommendations can also be affected by biases in the seed papers.
- It cannot guarantee full-text access, the integrity of searches, the quality of the papers, or the accuracy of citations; important information must be verified by referring to the original papers and specialized databases.
- The free version allows up to 50 seeds per query; although RR+ raises this limit to 300 seeds and adds filtering options, it is still not an automated systematic review tool.
- Before making the collection publicly available, it is necessary to check the notes and any unpublished research information.
Frequently Asked Questions
Is ResearchRabbit free?
There is a permanent free version that offers unlimited searches, unlimited collections, a citation map, collaboration features, and up to 50 seed papers – enough to carry out most focused literature searches.
How much is RR+?
The monthly fee is 12.5 dollars, while the annual fee is 120 dollars; this amounts to 10 dollars per month when calculated on an annual basis. Countries and regions that meet the requirements, such as China, can view the discounts on the upgrade page after logging in.
Can ResearchRabbit use AI to generate paper abstracts?
The core recommendation is to avoid using large language models, and instead rely on citations, co-citations, as well as author and co-author networks. The abstracts and metadata come from academic data sources, but it is still necessary to verify the original texts.
Can it be synchronized with Zotero?
Currently, it is possible to import Zotero collections, and to bring newly discovered items back into Zotero using BibTeX; full two-way synchronization as described in the official documentation is still under development.
Can it replace Google Scholar, PubMed, or Web of Science?
It’s not possible. It is suitable for enhancing network discovery and citation tracking, and should be used in conjunction with library databases and discipline-specific databases.
Is ResearchRabbit open source?
It is not open source. The official GitHub repository does not make available the source code for the full search, mapping, and recommendation functions; third-party repositories with the same name are not official products.
Tools similar to ResearchRabbit
 Guigong Network Security Registration No. 45132202000164